HTTP 503 Through a Proxy: Check Retry-After, Overload, and Upstream Capacity
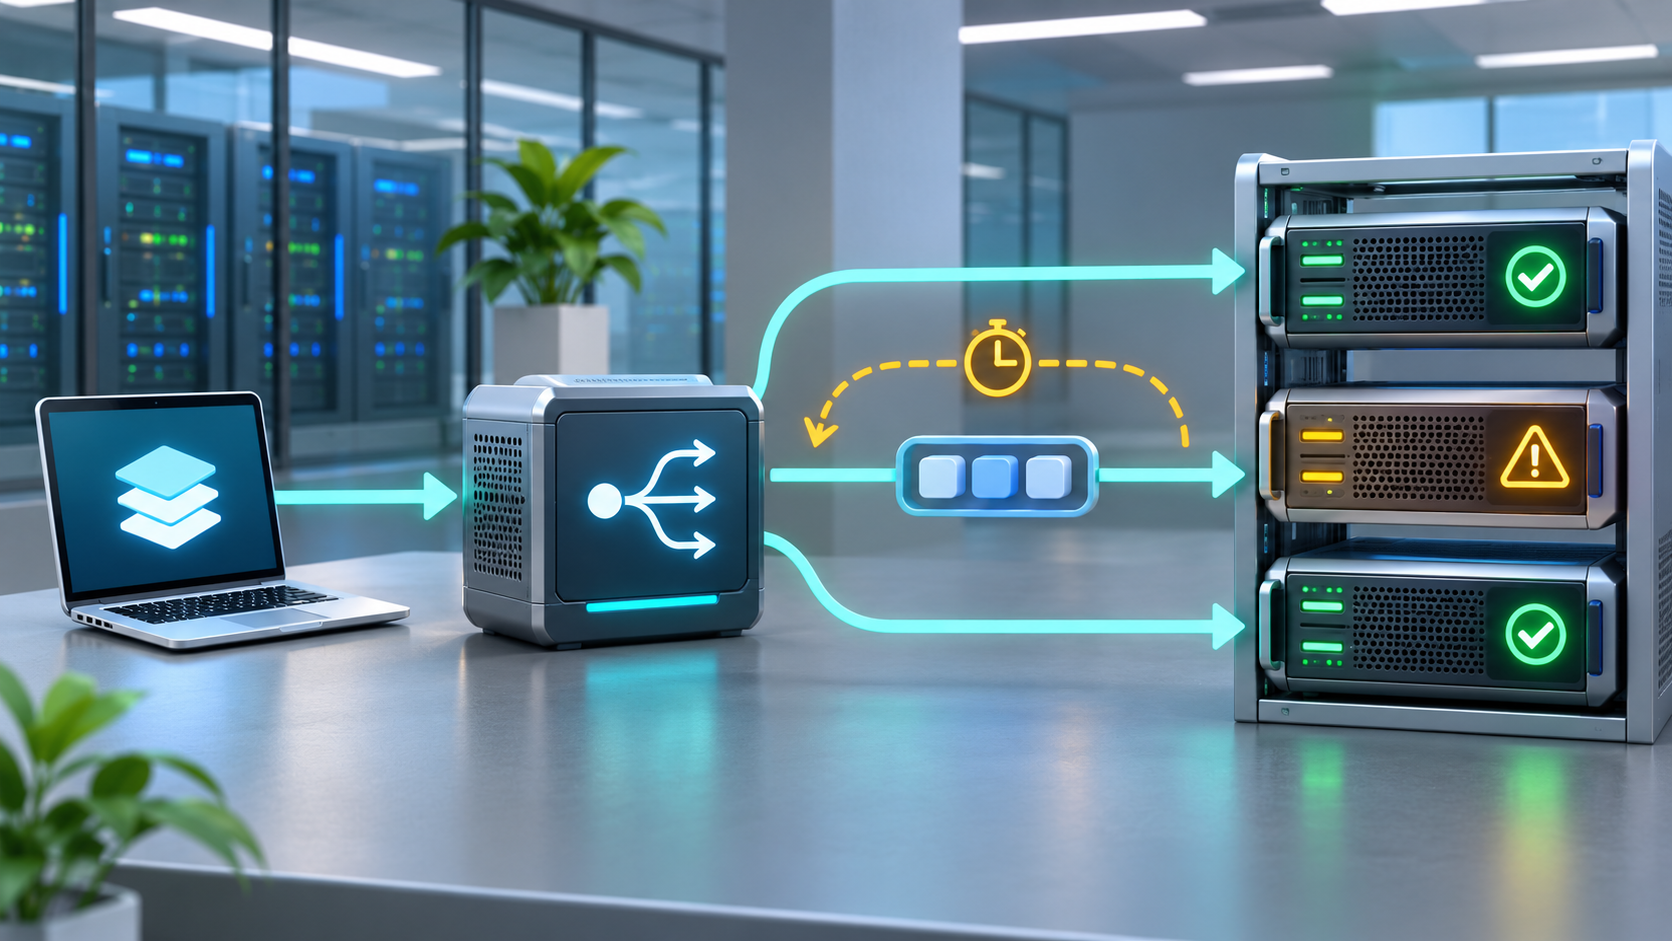
An HTTP 503 response through a proxy means one hop is temporarily unable to serve the request. The response may come from the proxy gateway, an edge or load balancer, or the target service. It does not, by itself, prove that the proxy exit is blocked or that replacing the IP will fix the problem.
Preserve the exact URL, method, timestamp, response headers, safe response-body summary, proxy protocol, endpoint, exit address, and elapsed time before changing anything. The immediate job is to identify the response owner, respect any waiting instruction, reduce load, and decide whether a controlled route comparison is justified.
Separate temporary unavailability from transport and rate-limit failures
| Observed result | Likely layer | Evidence to inspect | Next action |
|---|---|---|---|
| 503 on direct and proxy paths | Target, edge, or shared upstream | Server, Via, maintenance message, Retry-After | Wait and run one low-rate retest |
| 503 only through one fixed proxy | Proxy route or regional upstream | Gateway markers, exit region, DNS, timing | Keep the request fixed and compare one route |
| 503 only at higher concurrency | Capacity, pool, or queue pressure | Threads, active connections, queue time | Reduce load before any route change |
| 429 with rate-limit headers | Request-rate policy | Limit headers and reset time | Use the rate-limit branch |
| No HTTP status | DNS, connect, protocol, or TLS | Resolver, socket, handshake, timeout | Resolve transport first |
If there is no HTTP response, use the connection error comparison before diagnosing 503. A timeout with no response and a received 503 require different evidence and different recovery steps.
1. Identify the hop that returned the 503
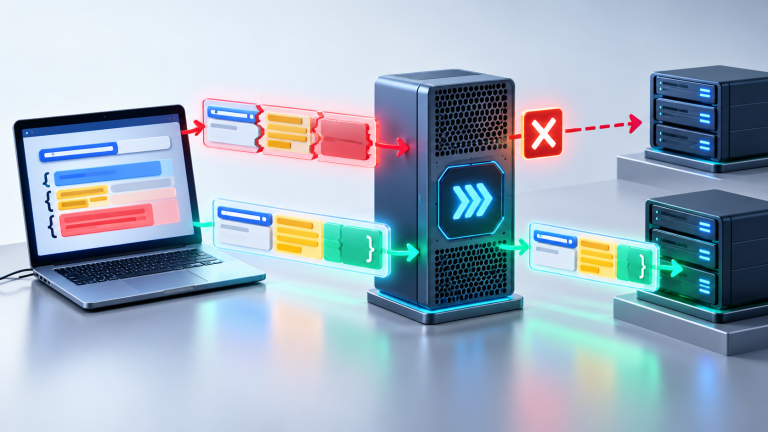
Capture the final host, status, Server, Via, cache markers, request identifier, Date, and the first safe lines of the response body. A proxy-specific gateway page points to the intermediary. A response branded or signed by the target host points to the target or its edge layer.
A pass is an unambiguous response owner. A fail is a screenshot with no headers. An ambiguous result is a response whose host, gateway, and body markers disagree. Keep the request read-only and ask the route owner to confirm the boundary before retrying at scale.
2. Build one direct-versus-proxy comparison
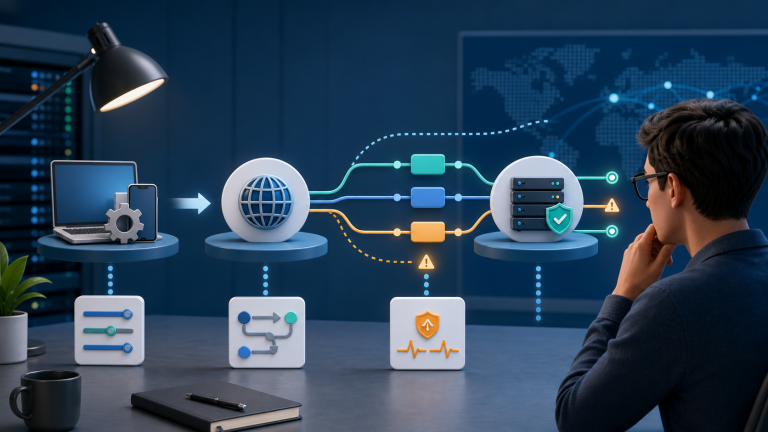
Fix the client version, method, target URL, headers, body, time window, and proxy endpoint. Send one direct request and one request through a fixed proxy with redirects and retries disabled. Record status, final URL, response owner, DNS time, connect time, time to first byte, total time, and exit address.
If both paths return the same 503, the target or a shared upstream is the leading branch. If only the proxy path fails, inspect regional routing, DNS, connection reuse, and gateway capacity. One comparison is a lead, not proof of root cause.
3. Read Retry-After as seconds or an HTTP date
Retry-After may contain a delay in seconds or a specific HTTP date. Compare a date value with the response Date header and convert it carefully to your local clock. Record the raw value, interpreted wait, response time, and planned next attempt.
Do not refresh continuously during the waiting period. When the delay expires, send one minimal read-only request. If the response remains 503, increase the interval and preserve the new sample rather than compressing the retry schedule.
4. Distinguish planned maintenance, overload, and regional failure
Planned maintenance often has a stable time window or consistent response page. Overload may correlate with concurrency, queue time, or traffic peaks. A regional problem may affect one exit region while another path remains healthy. Compare the same target and method in a narrow time window; do not compare unrelated pages or workloads.
Use a request timing baseline to separate normal warm-up, burst behavior, retry delay, and target response time. Recovery after a traffic drop is useful evidence, but it does not reveal a private server capacity limit unless the operator confirms it.
5. Check concurrency, queue depth, and shared exits
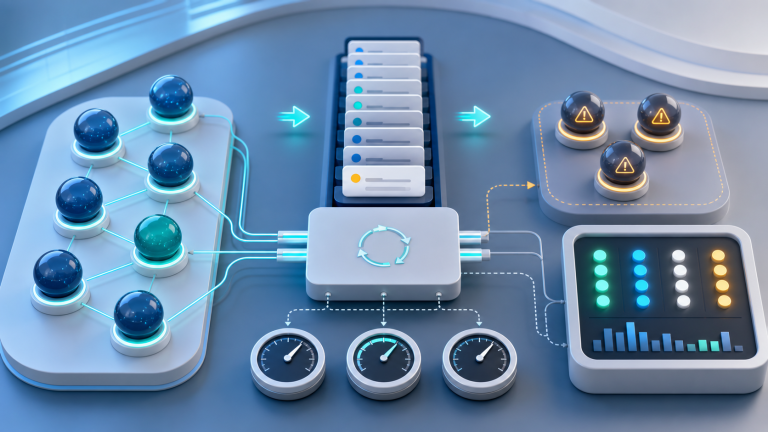
Reduce client concurrency to one, pause new queue entries, and confirm whether multiple workers share the same endpoint or exit. Record active connections, queued tasks, requests per minute, failure ratio, and the first time 503 appeared. Repeat once with the reduced load.
If low concurrency succeeds, keep the lower level and increase gradually only after stable checks. Do not claim that the proxy or target has a specific capacity threshold without administrative evidence. State only what was observed under the recorded workload.
6. Inspect connection pools and stale keep-alive sessions
A healthy client-to-proxy connection does not guarantee a healthy proxy-to-target connection. Pool exhaustion, stale reused sockets, upstream keep-alive limits, or a drained backend can all contribute to temporary unavailability. Close the test connection, create one fresh connection, and send one minimal request.
If a fresh connection succeeds while a reused connection fails, record connection age, idle time, pool size, and failure location. Change only one pool or timeout setting per test. Rotating exits at the same time would destroy the comparison.
7. Keep retries bounded and safe
Retry only when the request is read-only or explicitly idempotent, the response owner is known, and any stated wait has elapsed. Prefer the server’s delay. Without one, use progressively longer waits with small random variation so workers do not retry in lockstep.
Set a maximum attempt count, total wait budget, and stop condition. Review the proxy retry storm guide before enabling automatic recovery across a worker fleet. Never automatically repeat payments, submissions, messages, or state changes when the previous outcome is unknown.
8. Apply pass, fail, ambiguous, and stop conditions
| Outcome | Required evidence | Next action |
|---|---|---|
| Pass | Two low-rate requests return the expected response after the wait | Resume gradually and monitor |
| Fail: shared service | Direct and proxy paths return the same owned 503 | Keep traffic paused and wait for recovery |
| Fail: route-specific | Only one fixed proxy path repeatedly returns an owned 503 | Compare one controlled alternative route |
| Ambiguous | Identical attempts alternate without a fixed timing or path pattern | Rebuild the sample with one worker and one connection |
| Stop | Response owner is unknown or the request may have side effects | Stop retries and escalate with redacted evidence |
9. Record the evidence before changing the route
For each attempt, record timestamp, target, method, response owner, Retry-After, endpoint, exit address, concurrency, connection age, timing phases, changed variable, outcome, and stop decision. Use a proxy error log template so application and network owners receive the same evidence.
Also compare the exit with routine proxy pool health checks. A healthy general endpoint test does not invalidate a target-specific 503, but it helps separate broad proxy degradation from one target path.
10. Change the proxy route only after controlled checks
A route change is diagnostic only when the direct path is healthy, one fixed proxy path repeatedly returns 503, the wait has elapsed, and load, connection reuse, and request construction have been controlled. Keep the target, method, headers, body, and time window unchanged while testing one alternative from the available proxy service options.
A successful alternative route does not prove the first exit was defective. Retain both response chains and timing records so the responsible operator can determine whether the difference came from region, routing, DNS, gateway capacity, or target policy.
Conclusion: identify the owner, wait correctly, then reduce load
For HTTP 503 through a proxy, identify who returned the response, compare one direct and one fixed proxied request, interpret Retry-After, separate maintenance from overload, reduce concurrency, inspect connection reuse, and enforce bounded retries. Require repeatable pass conditions before restoring normal traffic.
Stop when the response owner is unclear, the wait has not expired, variables are not fixed, or the request can create side effects. A controlled timeline is more useful than a burst of replacement IPs and overlapping retries.