Proxy Exit Quarantine: When to Remove, Retest, and Return an IP to the Pool
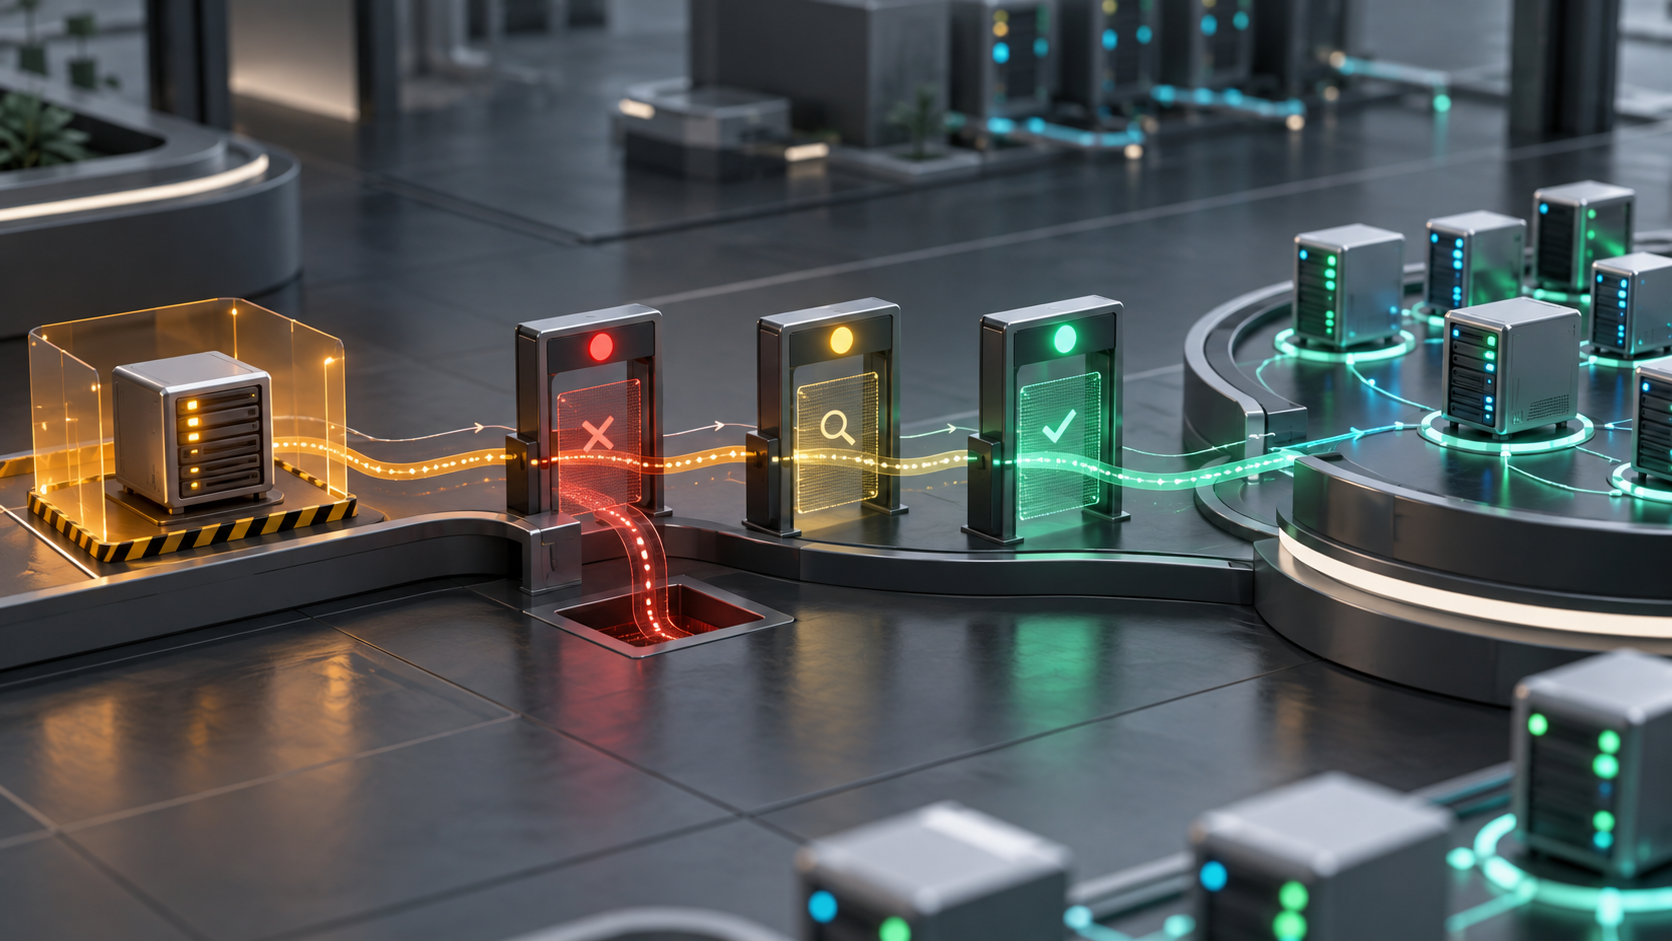
A proxy exit quarantine is a temporary operating state for an IP that has produced uncertain or repeated failures. Instead of immediately deleting the exit or continuing to send normal traffic through it, quarantine removes it from production, preserves the evidence, and creates a controlled path for retesting.
The goal is not to prove that an IP is universally good or bad. It is to answer a narrower question: is this exit ready for this target, region, protocol, and traffic class again? A useful process separates endpoint faults from authentication, DNS, target response, rate limits, and client-side timing before making that decision.
Use quarantine when the evidence is incomplete
Remove an exit from active traffic when failures repeat beyond the lane’s normal baseline, when the same exit fails across independent clients, or when a change in region, ASN, protocol, or authentication state cannot yet be explained. One isolated timeout is usually weak evidence. A cluster of failures with the same signature is stronger.
| Observed signal | Immediate action | Evidence to preserve |
|---|---|---|
| Repeated connection or TLS failures | Quarantine after the defined retry budget | Timestamp, protocol, connect time, target, client |
| Authentication fails across two clients | Pause the exit and verify credentials or whitelist state | Status code, auth method, source IP, credential version |
| Location or ASN changes unexpectedly | Hold region-sensitive traffic | Observed IP, region sources, ASN, prior assignment |
| Target returns 403 or 429 | Separate target policy from endpoint health | Response headers, request rate, target path, comparison exit |
| Latency rises without hard failure | Reduce load and compare timing stages | DNS, connect, TLS, first-byte, total time |
If the signal is still ambiguous, consult the established endpoint health checks before assigning a cause. Quarantine should protect production while diagnosis continues; it should not become a label that replaces diagnosis.
Record the quarantine reason before changing anything
Create one record per exit and incident. Capture the exit identifier, first and last failure time, protocol, region, authentication mode, affected target, traffic lane, failure signature, comparison exits, and the operator who made the decision. Also record whether the exit is static, sticky, or rotating because the retest meaning changes with assignment behavior.
A shared change log template prevents a repaired credential, client setting, or target rule from being mistaken for spontaneous IP recovery. Without that history, teams often return an exit to service without knowing what changed.
Stop production traffic without destroying the test case
Remove the exit from normal selection, but keep its configuration available to the validation lane. Disable automatic retries from production workers so repeated failures do not distort the next test. Preserve the same protocol and authentication fields unless one of those fields is the explicit test variable.
When a failure surge is already amplifying itself, apply the existing retry storm controls first. Retesting an exit while uncontrolled retries continue produces noisy evidence and can make a healthy recovery look unstable.
Retest in layers, not with one generic IP check
- Reachability: verify DNS resolution where relevant, TCP connection, and TLS negotiation without production concurrency.
- Authentication: confirm username and password or source-IP whitelist behavior with a known-good client.
- Identity: record the actual outbound IP, expected region, ASN, and whether the assignment remained stable for the required interval.
- Target response: test the intended target with a low request rate and compare a known-good exit under the same conditions.
- Timing: separate connect time from target response time and compare results with the normal request timing baseline.
Change one variable at a time. If protocol, client, target, credentials, and exit all change together, a passing result does not reveal which layer recovered. Use the same small validation request set for both the quarantined exit and a healthy control.
Define pass, fail, and ambiguous outcomes
| Outcome | Minimum evidence | Next step |
|---|---|---|
| Pass | Repeated successful checks across the required protocol and target, with timing inside the accepted range | Move to limited re-entry |
| Fail | The original signature repeats after client, auth, and target comparisons | Keep quarantined, replace, or escalate |
| Ambiguous | Mixed results, changing outbound IP, inconsistent geo data, or target-only errors | Extend observation and isolate another variable |
| Configuration fault | A credential, whitelist, protocol, or client correction resolves the issue | Document the correction, then retest from the start |
Do not use a single successful request as the whole pass condition. Define a small consecutive-success requirement, a maximum accepted latency range, and the exact targets that matter. Equally, do not interpret every 403 or 429 as proof that the exit itself is broken.
Return the exit through a limited traffic lane
Re-entry should be gradual. Start with low-risk validation traffic, a limited request budget, and no automatic promotion to sensitive login or session-bound work. Observe success rate, connection errors, response classes, and timing for a defined window. Expand only when the original failure signature stays absent.
For larger pools, keep a dedicated validation lane and a separate production lane. Use consistent pool health metrics across both lanes, but give each target and traffic class its own acceptance criteria. General inventory size does not replace target-specific validation.
Set stop conditions before re-entry begins
Return the exit to quarantine immediately if the original signature repeats, the outbound identity changes unexpectedly, authentication becomes inconsistent, or timing crosses the lane’s rollback threshold. Stop testing if the target response suggests policy or rate limiting that cannot be distinguished safely from endpoint health.
Operators should also stop when they lack a known-good comparison exit, when time sources or logs are inconsistent, or when the assignment model makes the tested IP different from the one that failed. In those cases, the evidence does not support a re-entry decision.
Use a compact re-entry checklist
- The original failure signature and traffic lane are recorded.
- Production retries are no longer touching the quarantined exit.
- Protocol, authentication, outbound IP, region, and ASN have been checked.
- A healthy control exit has been tested under the same client and target conditions.
- Timing is compared by stage rather than by total duration alone.
- Pass, ambiguous, and rollback thresholds are written before rollout.
- Limited re-entry has an owner, observation window, and request budget.
- The final decision and configuration changes are stored in the incident record.
Make quarantine a reversible operating state
A quarantine process works when it protects active traffic and improves the next decision. It should be easy to see why an exit was removed, what was retested, what changed, and which evidence justified re-entry. For teams designing the wider setup, compare proxy service options by assignment model, authentication, region controls, and observability rather than treating every exit as interchangeable.
The practical sequence is simple: isolate, preserve evidence, retest one layer at a time, classify the result, and restore traffic gradually. That sequence avoids both premature replacement and premature return.