Proxy Request Timing Baseline: Separate Warm-Up, Burst Traffic, Retries, and Timeouts
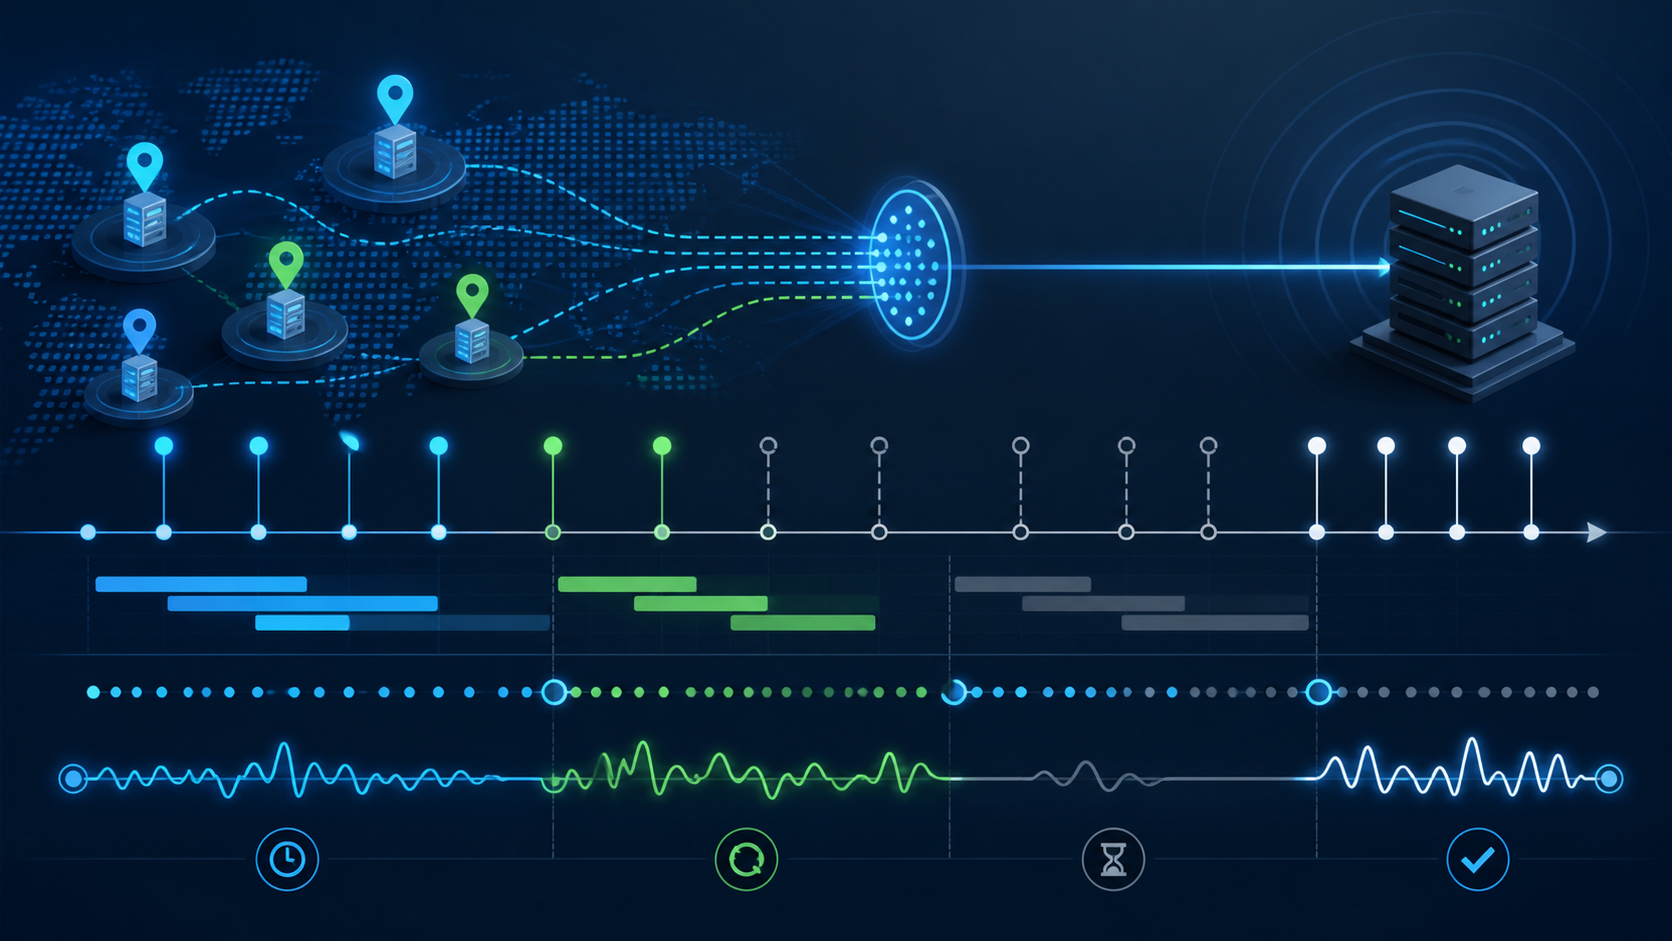
A proxy request timing baseline is the reference pattern you compare against when traffic starts failing. Without it, every timeout can look like a bad IP, every retry can look like a target block, and every slow response can lead to unnecessary rotation. The baseline gives you a controlled way to separate warm-up behavior, burst traffic, retry pressure, timeout settings, and target-side throttling.
The practical rule is simple: test one proxy exit with a small, repeatable request pattern before you increase volume. Record connection time, first response time, status code, retry count, timeout threshold, and the delay between requests. If the exit behaves normally at a calm pace but fails during a sudden burst, the issue is probably timing pressure, not just IP quality.
What A Timing Baseline Should Answer
The baseline should answer four questions before you scale: how long the first request takes, how stable repeated requests are, when retries begin to stack, and which timeout limit turns a slow response into a failure. These fields matter because proxy operations often fail gradually before they fail completely.
For a residential proxy pool, timing also helps you avoid blaming the wrong layer. A slower first connection may come from DNS resolution, session assignment, target-side warm-up, or the network path. Treat timing as a diagnostic layer that sits beside location, reputation, and protocol checks.
Baseline The Calm Path First
Start with a low-volume control test. Use the same proxy endpoint, protocol, authentication method, target URL, request headers policy, and user action you expect to repeat later. Send a small number of requests with generous spacing. Record DNS lookup time if available, connect time, TLS handshake time for HTTPS traffic, first byte time, full response time, status code, redirect behavior, and timeout result.
This control path gives you the cleanest reference. If the calm path already has unstable latency, do not continue into concurrency tests. Run a focused latency check first and separate DNS, connection time, and target response time before changing exits.
Then Add One Pressure Variable At A Time
After the calm path is stable, increase only one timing variable. You can shorten the delay between requests, raise concurrency, add retries, or reduce the timeout. Do not change all of them together. If several timing settings move at once, the result may show failure without explaining which setting caused it.
| Timing Variable | What To Change | What To Watch | Stop Condition |
|---|---|---|---|
| Warm-up | Compare first request with later requests | Slow first byte, redirects, or authentication delay | First request repeatedly times out |
| Request spacing | Shorten delay between requests in small steps | Status changes, challenge pages, or rising latency | Failures appear only after spacing is reduced |
| Burst size | Raise request count in a short window | Timeout clusters and inconsistent status codes | Failures cluster during the burst window |
| Retries | Add limited retries with backoff | Retry queue growth and duplicate failures | Retries create more load than successful recovery |
| Timeout | Test realistic timeout thresholds | Slow success versus hard failure | Useful responses are cut off by a too-short threshold |
Separate Warm-Up From Degradation
A warm-up delay happens at the beginning of a controlled session and then settles. Degradation gets worse as requests continue. Those two patterns need different actions. Warm-up may call for a longer first-request timeout, a small preflight request, or a slower first action. Degradation usually calls for lower concurrency, better spacing, fewer retries, or quarantine of the exit.
When you record the baseline, mark the first request separately from the steady-state requests. If the first request is slow but the next five are stable, that is not the same as an exit that slows down on every request. This distinction keeps the endpoint check from becoming a vague pass/fail note.
Do Not Let Retries Hide The Real Failure
Retries are useful only when they recover from occasional failure without adding more pressure than the proxy or target can handle. A bad retry policy can turn a small timeout cluster into a larger traffic surge. That is why the baseline should record first attempt result, retry attempt count, backoff delay, final status, and total time spent on the request.
If retries mostly repeat the same failure, stop increasing traffic. Use retry control rules: cap retries, add backoff, quarantine repeated failures, and avoid sending a failed request back into the same pressure window. A proxy that looks unstable under retries may actually be reacting to the retry pattern.
Use A Small Ramp Before Full Concurrency
Concurrency should move in small steps after the calm path is known. For example, test one request at a time, then two, then five, then ten, with the same target path and timing record. The goal is not to find the highest possible number in one run. The goal is to find the point where response time, timeout rate, or target behavior begins to change.
A clean concurrency ramp should show which threshold changed first. Did connect time rise? Did first byte time rise? Did status codes change? Did retries start to queue? These observations are more useful than a simple note that the proxy failed under load.
Decision Table For Timing Results
| Result Pattern | Likely Meaning | Best Next Action |
|---|---|---|
| Slow first request, stable later requests | Warm-up or session setup cost | Use a longer first timeout or add a preflight check |
| Stable calm path, failures during bursts | Request spacing or burst size is too aggressive | Reduce burst size and increase spacing |
| Failures grow after retries | Retry pressure is amplifying the problem | Cap retries and add backoff before retesting |
| Latency rises with concurrency | The exit, client, or target cannot handle current parallel load | Lower concurrency and retest with the same target path |
| Timeouts occur at realistic spacing | Exit quality, route stability, or target response may be weak | Compare another exit before replacing the full pool |
Fields To Record In The Baseline
- Proxy endpoint, protocol, authentication method, and assigned exit IP.
- Target URL, request type, headers policy, and whether login state is involved.
- DNS lookup time, connect time, TLS handshake time, first byte time, and full response time when available.
- Status code, redirect behavior, challenge response, timeout result, and final content state.
- Request spacing, burst size, concurrency level, retry limit, and backoff rule.
- First request result, steady-state result, failure threshold, and stop condition.
- Decision: keep timing, slow down, cap retries, reduce concurrency, rotate, or quarantine.
When To Rotate And When To Slow Down
Rotation is not the first fix for every timing failure. Rotate when the same exit repeatedly fails under a calm baseline or when target response changes in a way that follows the exit rather than the traffic pattern. Slow down when failures appear only after request spacing tightens, bursts get larger, or retries stack up.
Use a documented rotation decision only after the timing evidence is clear. If you rotate too early, you may hide a bad client timeout, an aggressive retry loop, or a target path that needs slower handling. If you rotate too late, one weak exit can waste the entire test window.
A Practical Stop Rule
Stop the rollout when two timing signals fail in the same window. Examples include rising latency plus repeated retries, timeout clusters plus changed status codes, or stable calm tests followed by burst-only failures. At that point, scaling adds noise. Pause, reduce traffic, return to the baseline, and change only one timing setting before testing again.
A proxy request timing baseline is useful because it prevents overreaction. It helps you prove whether the next action should be slower spacing, fewer retries, a higher timeout, a smaller concurrency step, a new exit, or a temporary quarantine. That evidence is what keeps proxy troubleshooting from becoming guesswork during a scaling window.